A fluent answer can still be wrong. LLM evaluations (evals) are repeatable tests: give a system an input, examine its response, and score it against explicit criteria. They help you compare changes and uncover failures before users do.
What should you measure?
Start with the task. A support assistant needs factual, relevant answers grounded in the supplied policy; a data extractor needs correct fields and valid output. Score correctness, instruction following, grounding, and safety separately. Good formatting does not establish factual accuracy.
Use code checks for objective requirements, such as a JSON schema or a numerical answer. For open-ended responses, combine a clear rubric with human review or an LLM judge. Check the judge against expert ratings: it can reward confident wording or miss errors. Anthropic’s eval guide explains these grading tradeoffs.
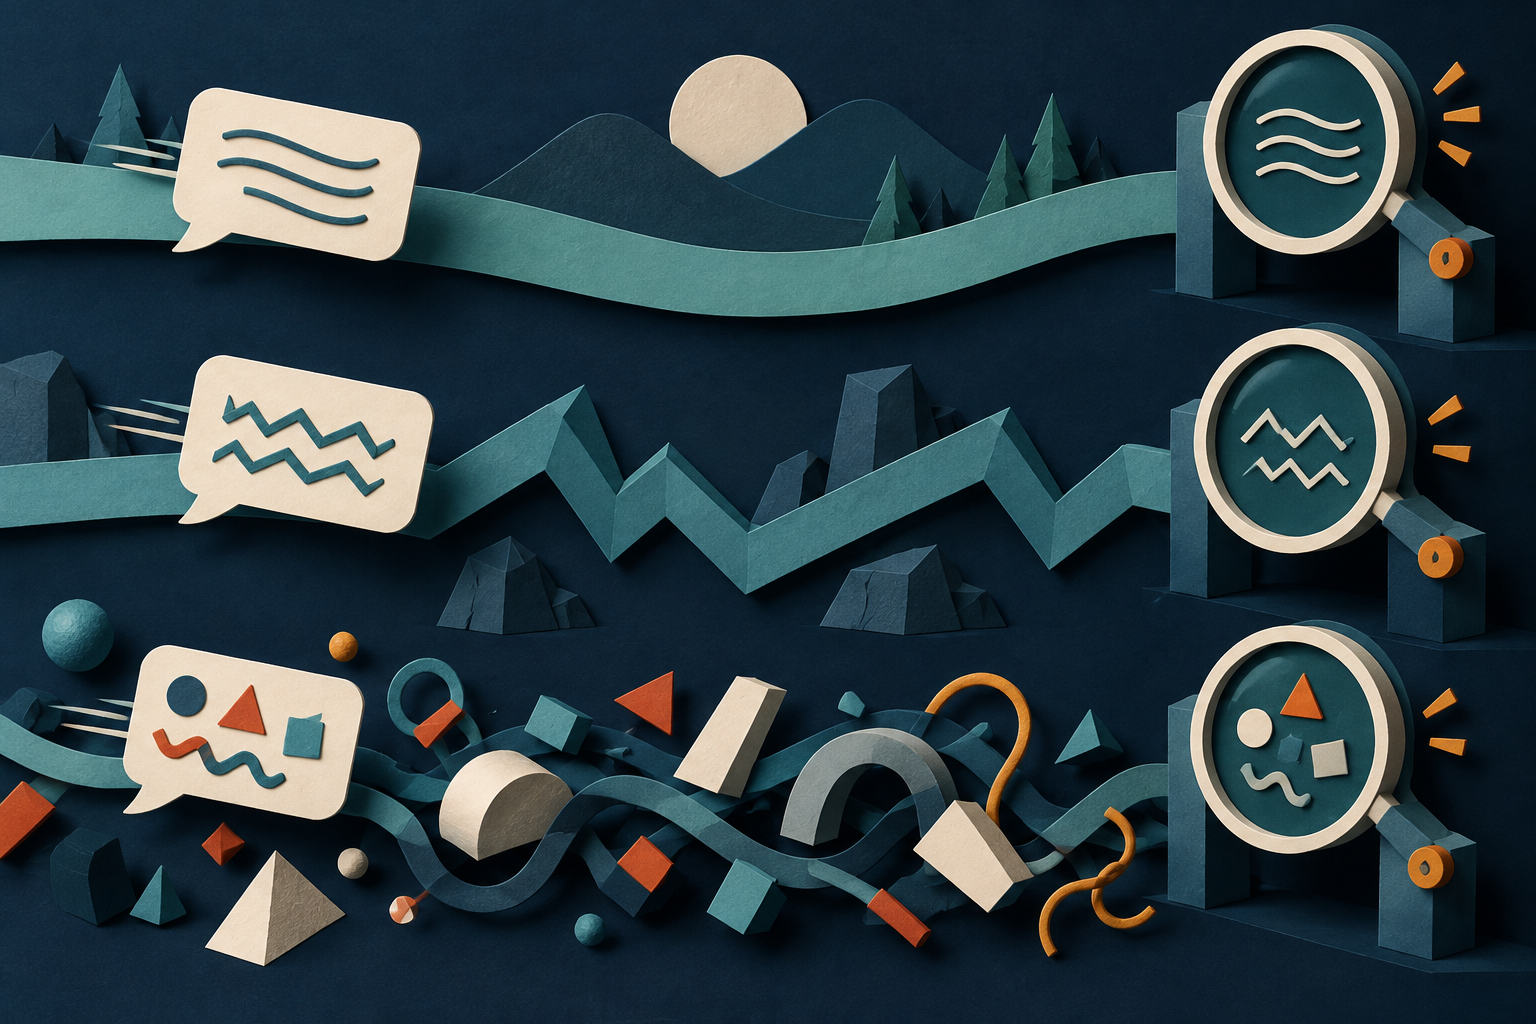
AI-generated illustration: test the same task under varied conditions.
Robustness means surviving variation
A robust system remains useful when realistic conditions change. Test paraphrases, typos, long or distracting context, missing evidence, and adversarial instructions inside retrieved material. Preserve the intended meaning when testing invariance; when the facts change, the correct answer should change too.
Example: a supplied policy allows returns within 30 days. Test “Can I return this after 20 days?” and a typo-filled version. Both should apply the same rule. Then remove the policy: the assistant should ask for it or acknowledge uncertainty, rather than invent a deadline.
Build a trustworthy test loop
- Collect representative requests plus difficult and previously failed cases. Define success before scoring.
- Keep a held-out test set separate from examples used to tune prompts. Test the actual system, including retrieval and tools.
- Repeat trials to expose output variability. Compare versions on the same cases and report sample sizes, uncertainty, and results by failure category—not just an average.
- Inspect failures, improve the system, and rerun regression tests after changes. Monitor real-world failures and add new cases.
A benchmark score is evidence about a particular test, not a guarantee of reliability everywhere. Multidimensional evaluation, as illustrated by Stanford’s HELM Instruct, makes the tradeoffs easier to see.
The goal is measurable improvement on the situations your users actually face.